FreeAttn: Unlocking Native E3M4 for Efficient and Accurate Attention
FreeAttn is a Dual-Free (zero-inner-loop-overhead) block-scaled attention framework on Blackwell Tensor Cores, beating SageAttention2++ in 8-bit speed and accuracy while extending to 8/4 and 4/4 NVFP4.
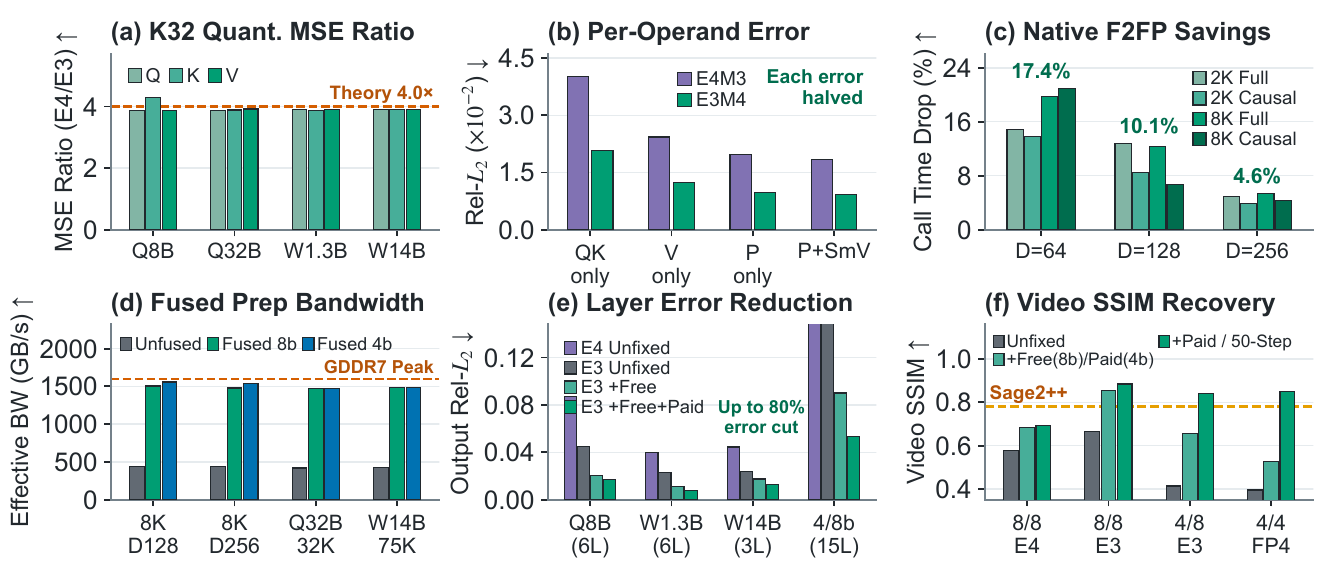
K = 32 UE8M0 scaling keeps 99.93% of energy in [0.25, 30.0], cutting MSE 3.82–4.62× vs. E4M3 at 1.000× QMMA.SF speed; 1-instruction F2FP packs online P in registers (+4.6%–17.4%).
Smooth-K/V, Scale-QK, and Hadamard-QK cancel algebraically across online softmax with zero inner-loop MMAs in one GDDR7 pass (1,467–1,559 GB/s vs. 420–445 GB/s unfused).
1. Multi-Step Video Generation (720p, 3D Orbit & VBench)
Matched initial noise and schedules on one RTX PRO 6000 Blackwell GPU (96 GB GDDR7); only self-attention is replaced.
1.1 Split-Screen Comparison (Wan2.1-T2V-14B: 720p & 3D Camera Orbit)
1.2 Nine-Scene Synchronized 2×4 Grids
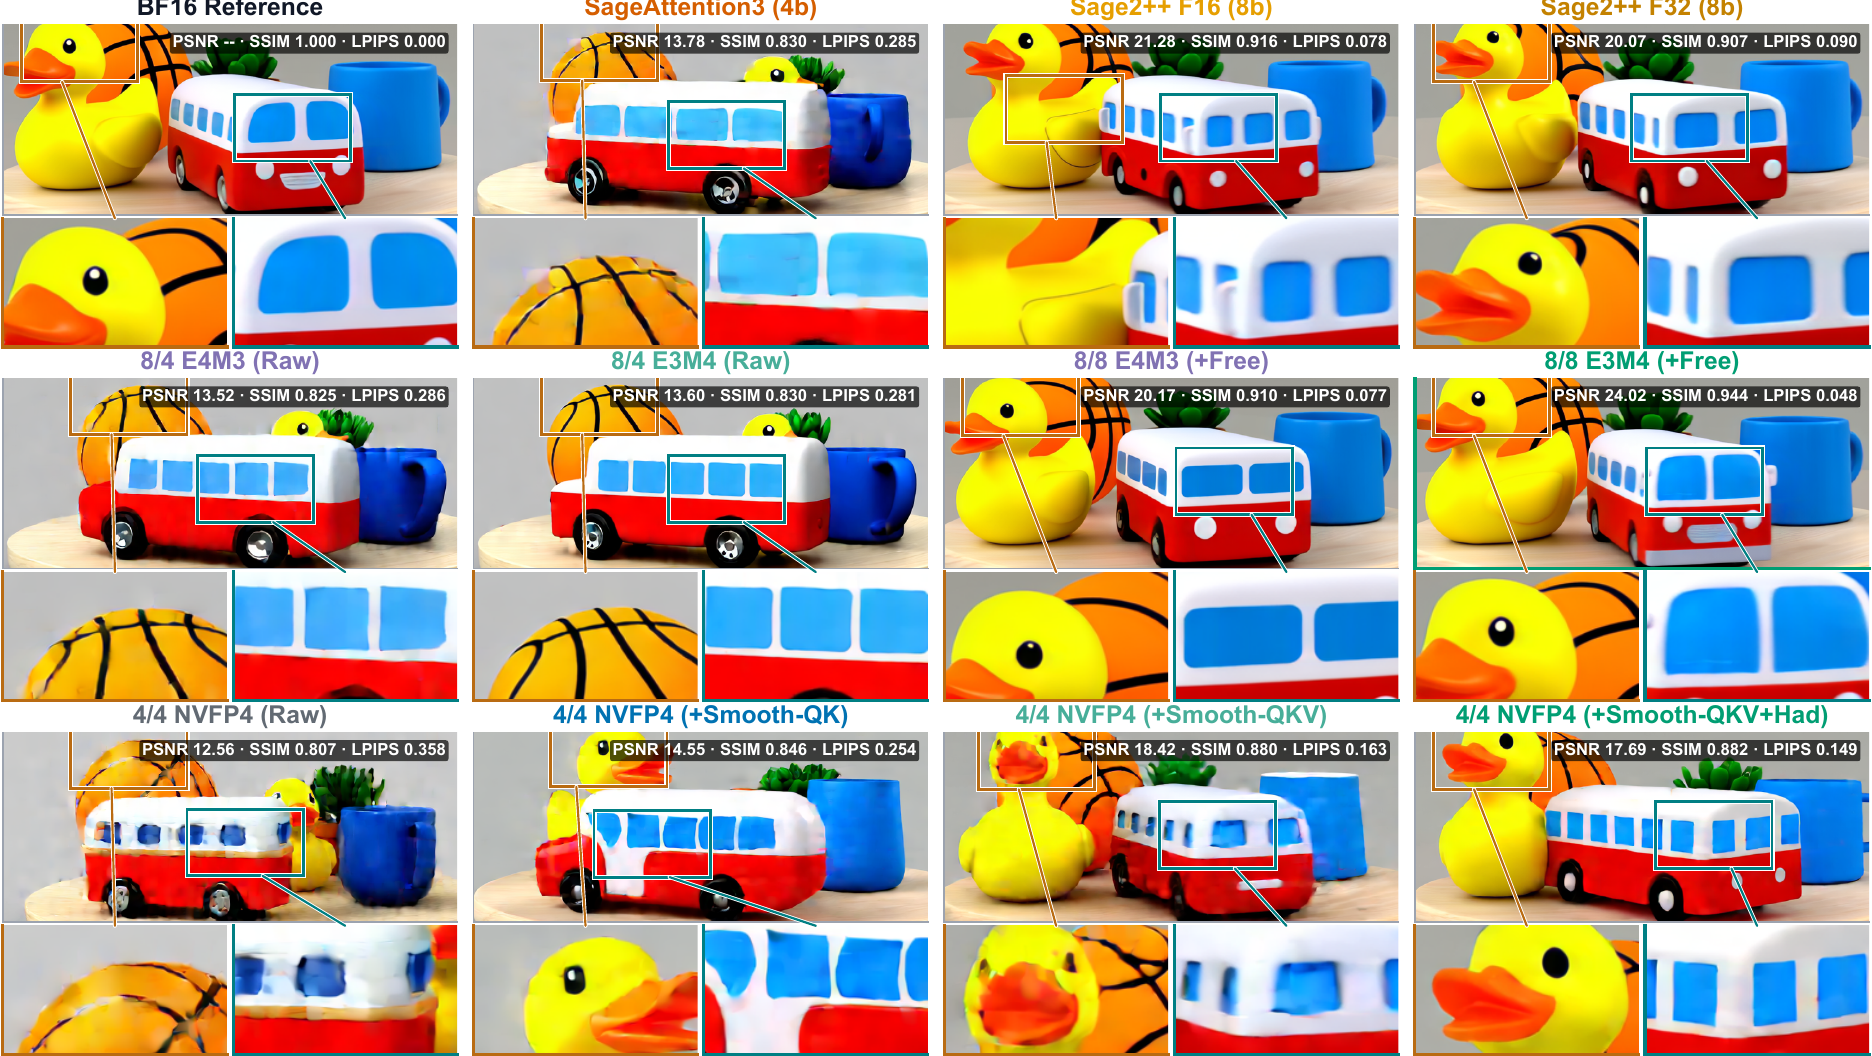
1.3 Bus-Front Crops & 4-Bit NVFP4 Recovery (Paper Fig. 1)
2. Language Models Across 8-Bit, 8/4 & 4-Bit NVFP4
Evaluated on GQA LLMs (Qwen3-8B / 32B, S ≤ 32K), where official SageAttention3 fails natively on GQA and collapses after 4× KV replication.
2.1 Low-Precision Spectrum (Qwen3-8B / 32B, 32K LongBench-v2 & KV)
RuntimeError: The size of tensor a (32) must match the size of tensor b (8) at non-singleton dimension 1
| Precision Tier & Method | GQA | 8B KL ↓ | 8B / 32B Agree ↑ | 8B Attn | KV (8B KL) | Behavior |
|---|---|---|---|---|---|---|
| PyTorch SDPA BF16 (Ref) | Yes | 0.00000 | 100% / 100% | 1.00× | 16b (0.0000) | Reference |
| FreeAttn 8/8 E3M4 (+Free) | Yes | 0.00325 | 100% / 100% | 1.99× | 8.25b (0.0087) | 32/32 exact |
| FreeAttn 8/8 E4M3 (+Free) | Yes | 0.00794 | 87.5% / 93.8% | 2.01× | 8.25b (0.0313) | 22.5K QA flip |
| SageAttention2++ (F16) | Yes | 0.00647 | 96.9% / 96.9% | 1.76× | 16b BF16 only | 22.5K QA flip |
| FreeAttn 8/4 E3M4 (+Free+Paid) | Yes | 0.02026 | 90.6% / 96.9% | 1.91× | 6.25b (0.0556) | Lossy; clean |
| FreeAttn 4/4 NVFP4 (+Free+Paid) | Yes | 0.02802 | 81.2% / 87.5% | 1.94× | 4.25b (0.2372) | 69.5% 5-task; clean |
| SageAttention3 4/4 NVFP4* | No | 1.86–2.90† | Fails / No GQA | — | — | EOS & ffff... |
2.2 Verbatim Outputs Across Precision Tiers (Qwen3-8B, Greedy)
3. Dual-Free Framework: Beyond ISA Probes & SageAttention2++
3.1 Dual-Free Co-Design vs. Static E3M4 ISA Probes
| Approach | Scaling & Online P | Outlier / Bias Control | Streaming Attention Result |
|---|---|---|---|
| Per-Tensor FP8 PTQ (Kuzmin'22; Shen'24) | Global / channel scale; no online P | Static range calibration | Spikes clip E3M4 → favors E4M3 |
| Public E3M4 ISA Probe (blackwell-isa'26) | Static QMMA.SF; no packed F2FP | None (static GEMM probe) | No attention kernel (Raw E3M4: 16.80 dB) |
| FreeAttn Dual-Free (Ours) | K=32 UE8M0 + 1-inst register F2FP | 1-pass Smooth-K/V + Scale/Had-QK | 3.82–4.62× lower MSE; 24.02 dB; 32/32 LB-v2 |
3.2 Why Faster & More Accurate Than SageAttention2++
4. Quantitative Benchmarks
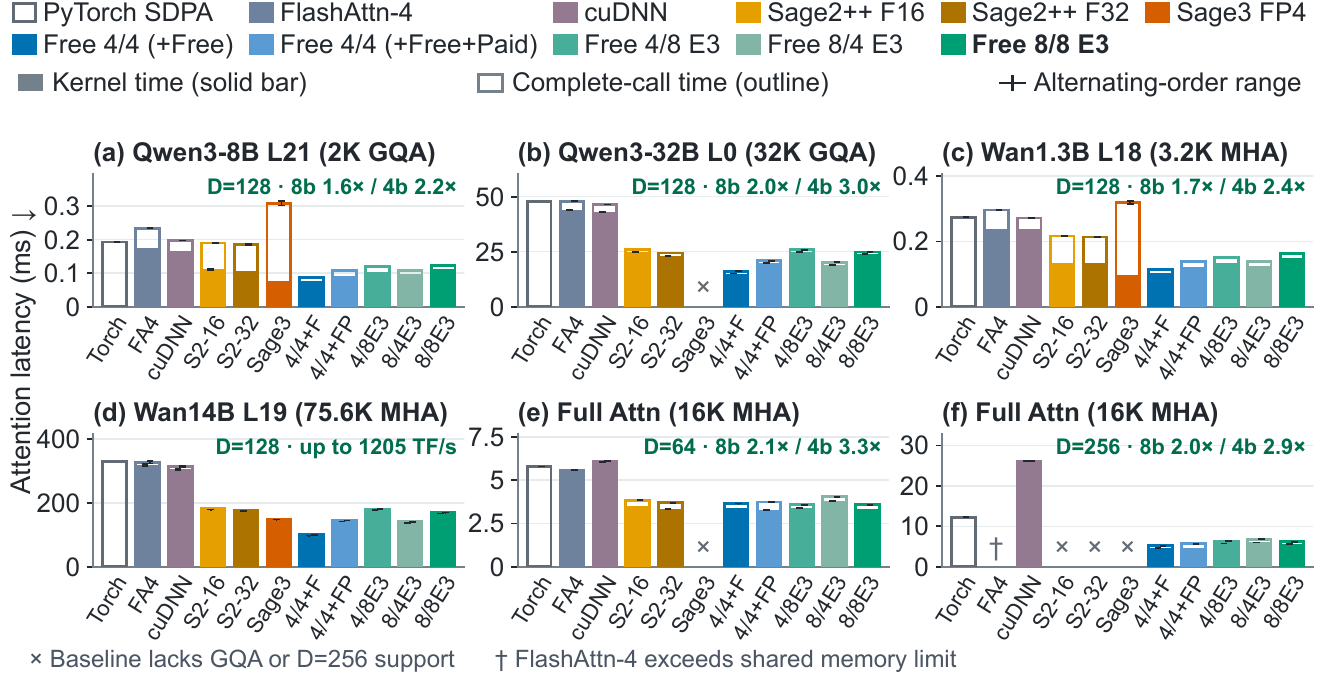
Single NVIDIA RTX PRO 6000 Blackwell GPU (96 GB GDDR7); complete-call timings include fresh-input preparation and post-processing.
| Implementation | QK⊤ | PV | Head Dimensions & Attention Types |
|---|---|---|---|
| PyTorch SDPA / cuDNN | BF16 | BF16 | D ∈ {64, 128, 256}, MHA & GQA |
| FlashAttention-4 | BF16 | BF16 | D ∈ {64, 128}, MHA & GQA |
| SageAttention2 / 2++ (F16 or F32 Acc) | INT8 | FP8 E4M3 | D ∈ {64, 128}, MHA & GQA (no D = 256) |
| SageAttention3 (Official Blackwell FP4) | NVFP4 | NVFP4 | D = 128 only, MHA only (no GQA, no D ∈ {64, 256}) |
| FreeAttn (Ours, Hardware QMMA.SF) | FP8 E3M4 / E4M3 or NVFP4 | FP8 E3M4 / E4M3 or NVFP4 | D ∈ {64, 128, 256}, Native MHA & GQA |
| Model / Suite | Configuration | 1-Step Rel-L2 ↓ | PSNR (dB) ↑ | SSIM ↑ | LPIPS ↓ | Attn (s) ↓ | Full Gen (s) ↓ |
|---|---|---|---|---|---|---|---|
| Wan2.1-1.3B (480p, 20-Step, 6-Scene) | PyTorch SDPA BF16 | 0.00000 | Ref | 1.0000 | 0.0000 | 4.71 (1.00×) | 19.47 (1.00×) |
| Wan2.1-1.3B (480p, 20-Step, 6-Scene) | SageAttention2++ (FP16) | 0.00593 | 23.37 | 0.8444 | 0.0877 | 2.79 (1.69×) | 17.53 (1.11×) |
| Wan2.1-1.3B (480p, 20-Step, 6-Scene) | SageAttention3 (NVFP4) | 0.01704 | 13.71 | 0.4636 | 0.4627 | 2.79 (1.69×) | 17.52 (1.11×) |
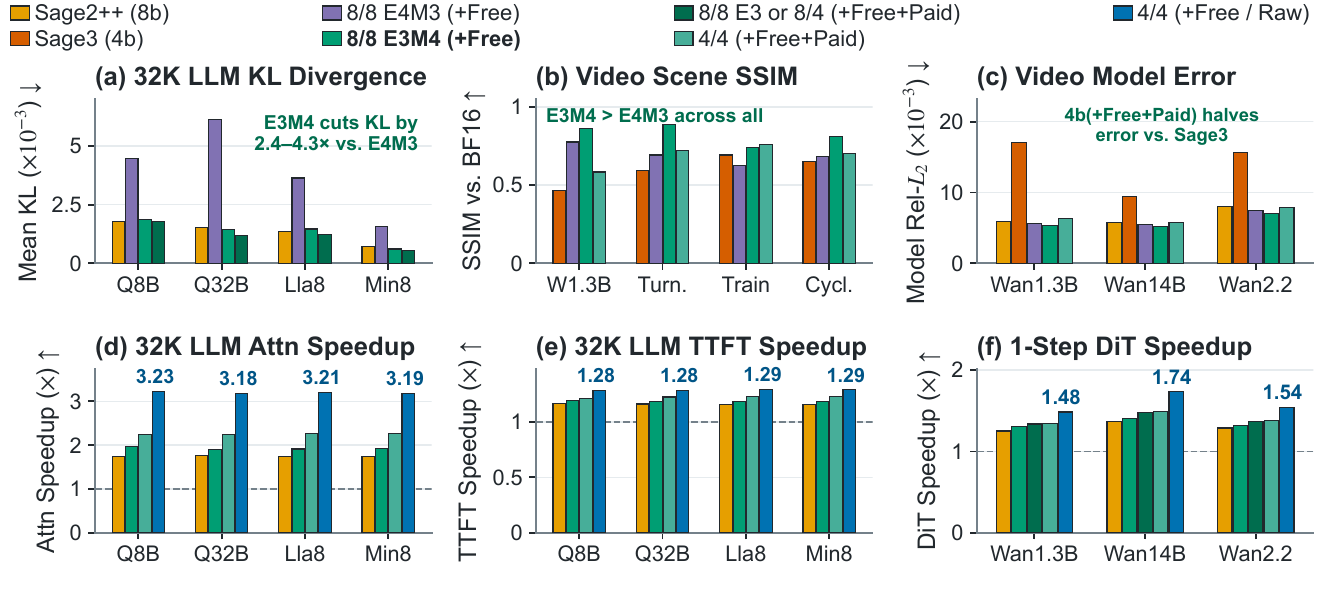
| Wan2.1-1.3B (480p, 20-Step, 6-Scene) | FreeAttn 8/8 E4M3 (+Free) | 0.00567 | 21.01 | 0.7747 | 0.1461 | 2.44 (1.93×) | 17.18 (1.13×) |
| Wan2.1-1.3B (480p, 20-Step, 6-Scene) | FreeAttn 8/8 E3M4 (+Free) | 0.00536 | 23.85 | 0.8605 | 0.0821 | 2.46 (1.92×) | 17.20 (1.13×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | PyTorch SDPA BF16 | 0.00000 | Ref | 1.0000 | 0.0000 | 12.77 (1.00×) | 2235.7 (1.00×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | SageAttention2++ (FP16) | 0.00572 | 21.28 | 0.9164 | 0.0775 | 6.96 (1.83×) | 1638.6 (1.36×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | SageAttention3 (NVFP4) | 0.00947 | 13.78 | 0.8295 | 0.2852 | 6.03 (2.12×) | 1517.2 (1.47×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | FreeAttn 8/8 E4M3 (+Free) | 0.00545 | 20.17 | 0.9103 | 0.0767 | 6.45 (1.98×) | 1561.9 (1.43×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | FreeAttn 8/8 E3M4 (+Free) | 0.00517 | 24.02 | 0.9435 | 0.0481 | 6.53 (1.96×) | 1569.7 (1.42×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | FreeAttn 4/4 NVFP4 (+Free+Paid) | 0.00572 | — | — | — | 5.81 (2.20×) | — |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | FreeAttn 4/4 NVFP4 (+Smooth-QKV+Had) | — | 17.69 | 0.8822 | 0.1494 | — | 1439.7 (1.55×) |
| Wan2.1-14B (720p×81f, 50-Step Turntable) | FreeAttn 4/4 NVFP4 (Raw) | 0.01263 | 12.56 | 0.8069 | 0.3580 | 3.64 (3.50×) | 1430.0 (1.56×) |
| Wan2.1-14B (480p, 20-Step, 4-Scene Mean) | SageAttention2++ (FP16) | 0.00643 | 22.02 | 0.8314 | 0.0961 | 11.60 (1.63×) | 81.61 (1.09×) |
| Wan2.1-14B (480p, 20-Step, 4-Scene Mean) | SageAttention3 (NVFP4) | 0.01069 | 16.24 | 0.6501 | 0.2665 | 13.05 (1.45×) | 83.07 (1.07×) |
| Wan2.1-14B (480p, 20-Step, 4-Scene Mean) | FreeAttn 8/8 E4M3 (+Free) | 0.00730 | 20.25 | 0.7888 | 0.1247 | 10.81 (1.75×) | 80.89 (1.10×) |
| Wan2.1-14B (480p, 20-Step, 4-Scene Mean) | FreeAttn 8/8 E3M4 (+Free) | 0.00595 | 22.41 | 0.8501 | 0.0811 | 10.92 (1.74×) | 80.99 (1.10×) |
| Model & Suite | Configuration | Mean KL ↓ | Agree ↑ | Seq Match ↑ | Attn (s) ↓ | TTFT (s) ↓ |
|---|---|---|---|---|---|---|
| Qwen3-8B · 32K Prefill (BF16: 0.889s / 2.583s) | SageAttention2++ (FP16) | 0.00179 | 99.02% | — | 0.512 (1.74×) | 2.222 (1.16×) |
| Qwen3-8B · 32K Prefill | FreeAttn 8/8 E4M3 (+Free) | 0.00446 | 97.66% | — | 0.449 (1.98×) | 2.181 (1.18×) |
| Qwen3-8B · 32K Prefill | FreeAttn 8/8 E3M4 (+Free) | 0.00187 | 98.63% | — | 0.451 (1.97×) | 2.174 (1.19×) |
| Qwen3-32B · 32K Prefill (BF16: 3.141s / 10.073s) | SageAttention2++ (FP16) | 0.00152 | 98.05% | — | 1.774 (1.77×) | 8.687 (1.16×) |
| Qwen3-32B · 32K Prefill | FreeAttn 8/8 E4M3 (+Free) | 0.00614 | 97.66% | — | 1.639 (1.92×) | 8.520 (1.18×) |
| Qwen3-32B · 32K Prefill | FreeAttn 8/8 E3M4 (+Free) | 0.00144 | 98.24% | — | 1.659 (1.89×) | 8.541 (1.18×) |
| Llama-3.1-8B · 32K Prefill (BF16: 0.792s / 2.470s) | SageAttention2++ (FP16) | 0.00137 | 98.97% | — | 0.456 (1.74×) | 2.131 (1.16×) |
| Llama-3.1-8B · 32K Prefill | FreeAttn 8/8 E4M3 (+Free) | 0.00363 | 98.36% | — | 0.409 (1.94×) | 2.081 (1.19×) |
| Llama-3.1-8B · 32K Prefill | FreeAttn 8/8 E3M4 (+Free) | 0.00146 | 98.92% | — | 0.414 (1.91×) | 2.087 (1.18×) |
| Ministral-3-8B · 32K Prefill (BF16: 0.841s / 2.618s) | SageAttention2++ (FP16) | 0.00072 | 99.24% | — | 0.485 (1.73×) | 2.260 (1.16×) |
| Ministral-3-8B · 32K Prefill | FreeAttn 8/8 E4M3 (+Free) | 0.00157 | 98.85% | — | 0.434 (1.94×) | 2.200 (1.19×) |
| Ministral-3-8B · 32K Prefill | FreeAttn 8/8 E3M4 (+Free) | 0.00061 | 99.25% | — | 0.439 (1.92×) | 2.210 (1.18×) |
| Qwen3-8B · LongBench-v2 (BF16: 0.488s / 1.70s) | SageAttention2++ (FP16) | 0.00647 | 96.9% | 78.1% | 0.278 (1.76×) | 1.49 (1.13×) |
| Qwen3-8B · LongBench-v2 | FreeAttn 8/8 E4M3 (+Free) | 0.00794 | 87.5% | 68.8% | 0.242 (2.01×) | 1.46 (1.16×) |
| Qwen3-8B · LongBench-v2 | FreeAttn 8/8 E3M4 (+Free) | 0.00325 | 100.0% (32/32) | 93.8% | 0.245 (1.99×) | 1.46 (1.16×) |
| Qwen3-8B · LongBench-v2 | FreeAttn 8/4 E3M4 (+Free+Paid) | 0.02026 | 90.6% | 78.1% | 0.256 (1.91×) | 1.46 (1.15×) |
| Qwen3-8B · LongBench-v2 | FreeAttn 4/4 NVFP4 (+Free+Paid) | 0.02802 | 81.2% | 59.4% | 0.252 (1.94×) | 1.45 (1.16×) |
| Qwen3-32B · LongBench-v2 (BF16: 1.706s / 6.43s) | SageAttention2++ (FP16) | 0.00427 | 96.9% | 75.0% | 0.947 (1.80×) | 5.68 (1.12×) |
| Qwen3-32B · LongBench-v2 | FreeAttn 8/8 E4M3 (+Free) | 0.00928 | 93.8% | 75.0% | 0.867 (1.97×) | 5.59 (1.14×) |
| Qwen3-32B · LongBench-v2 | FreeAttn 8/8 E3M4 (+Free) | 0.00407 | 100.0% (32/32) | 90.6% | 0.876 (1.95×) | 5.59 (1.14×) |
| Qwen3-32B · LongBench-v2 | FreeAttn 8/4 E3M4 (+Free+Paid) | 0.01730 | 96.9% | 78.1% | 0.908 (1.88×) | 5.61 (1.14×) |
| Qwen3-32B · LongBench-v2 | FreeAttn 4/4 NVFP4 (+Free+Paid) | 0.02722 | 87.5% | 81.2% | 0.895 (1.91×) | 5.56 (1.15×) |
| Implementation (ms / Rel-L2) | Qwen3-8B L21 | Qwen3-32B L0 (32K) | Wan1.3B L18 | Wan14B L19 (720p) |
|---|---|---|---|---|
| PyTorch SDPA (BF16) | 0.193 / 0.00172 | 47.75 / 0.00168 | 0.274 / 0.00168 | 328.72 / 0.00167 |
| FlashAttention-4 (BF16) | 0.234 / 0.00172 | 47.95 / 0.00168 | 0.296 / 0.00168 | 327.19 / 0.00211 |
| SageAttention2++ (FP16) | 0.190 / 0.03325 | 26.09 / 0.04127 | 0.217 / 0.00901 | 181.07 / 0.00974 |
| FreeAttn 8/8 E3M4 (+Free) | 0.124 / 0.02026 | 24.83 / 0.02283 | 0.163 / 0.00929 | 169.54 / 0.01085 |
| FreeAttn 8/8 E3M4 (+Free+Paid) | 0.156 / 0.01636 | 31.08 / 0.01614 | 0.214 / 0.00802 | 225.49 / 0.00971 |
| SageAttention3 (4/4 NVFP4) | 0.309* / 0.86897 | — (No GQA) | 0.319 / 0.06123 | 149.62 / 0.07232 |
| FreeAttn 8/4 E3M4 (+Free) | 0.108 / 0.08559 | 20.23 / 0.08186 | 0.139 / 0.02490 | 140.76 / 0.02749 |
| FreeAttn 4/4 NVFP4 (+Free+Paid) | 0.109 / 0.10536 | 20.92 / 0.09092 | 0.138 / 0.05477 | 144.98 / 0.06396 |
